Pinecone integrated embedding now supports OpenAI's text-embedding-3 models
Pinecone integrated embedding now supports OpenAI's text-embedding-3-small and text-embedding-3-large, alongside the Pinecone-hosted models it launched with. OpenAI's text-embedding-3 models are two of our most requested embedding models. Teams can now run semantic search on them without building and maintaining an embedding pipeline.
Set either model on a text field in a Documents API index and send plain text. Pinecone embeds every write and every query for that field with that model. There's no OpenAI account or key to manage, and the tokens appear on your Pinecone invoice at OpenAI's list price.
Through December 31, 2026, Starter and Builder plans get twice their included tokens for OpenAI's models: 10M a month on each model for Starter and 20M a month on each model for Builder.
Let Pinecone make the embedding calls
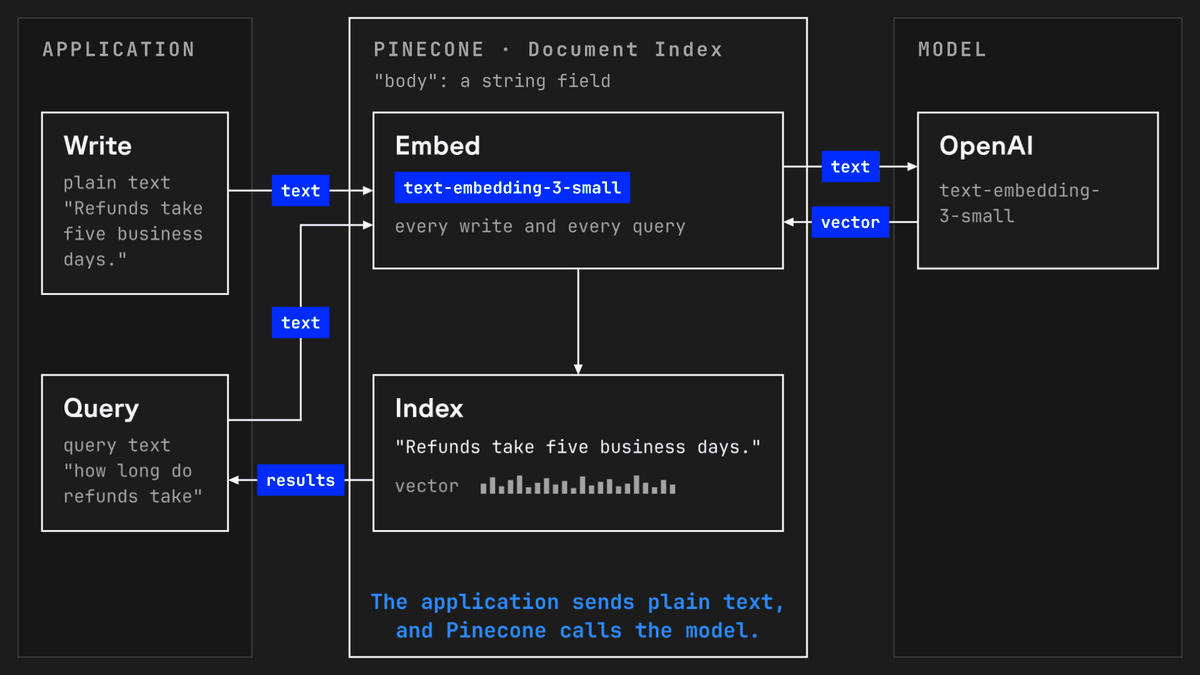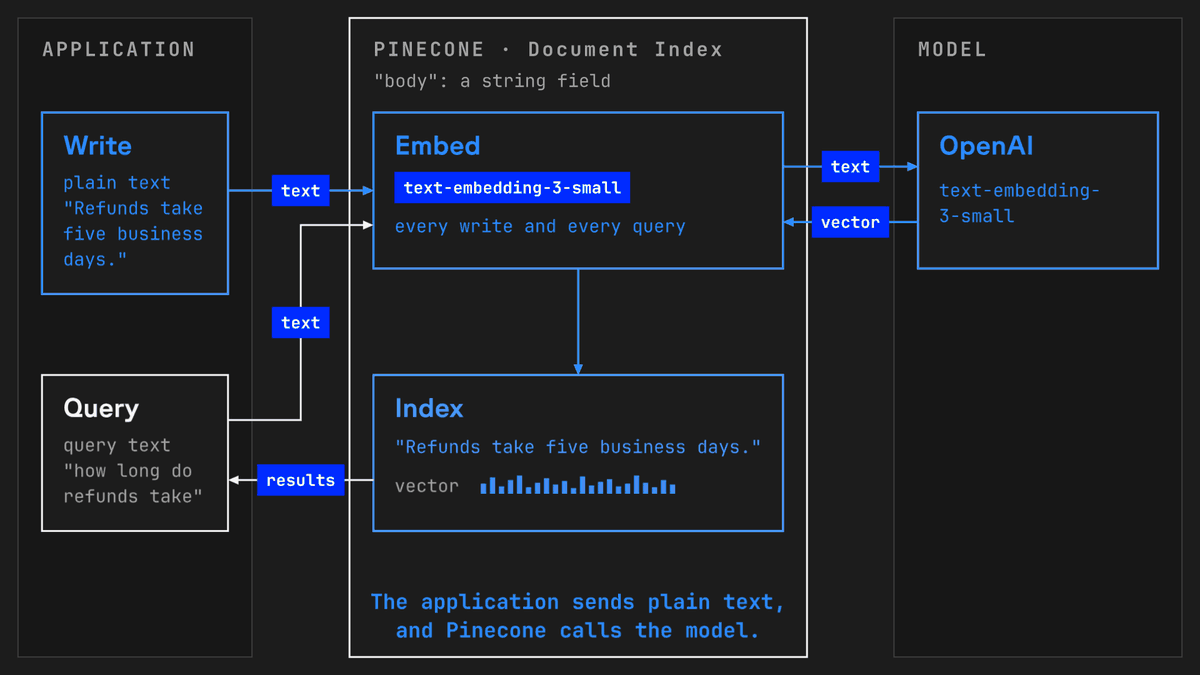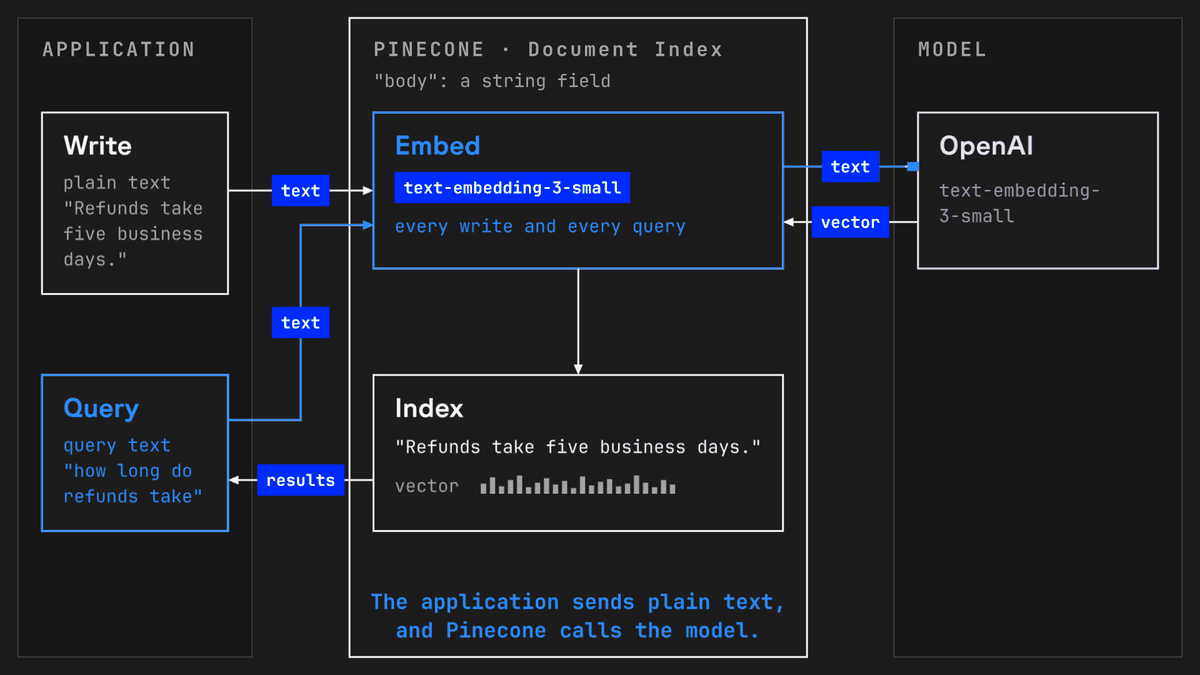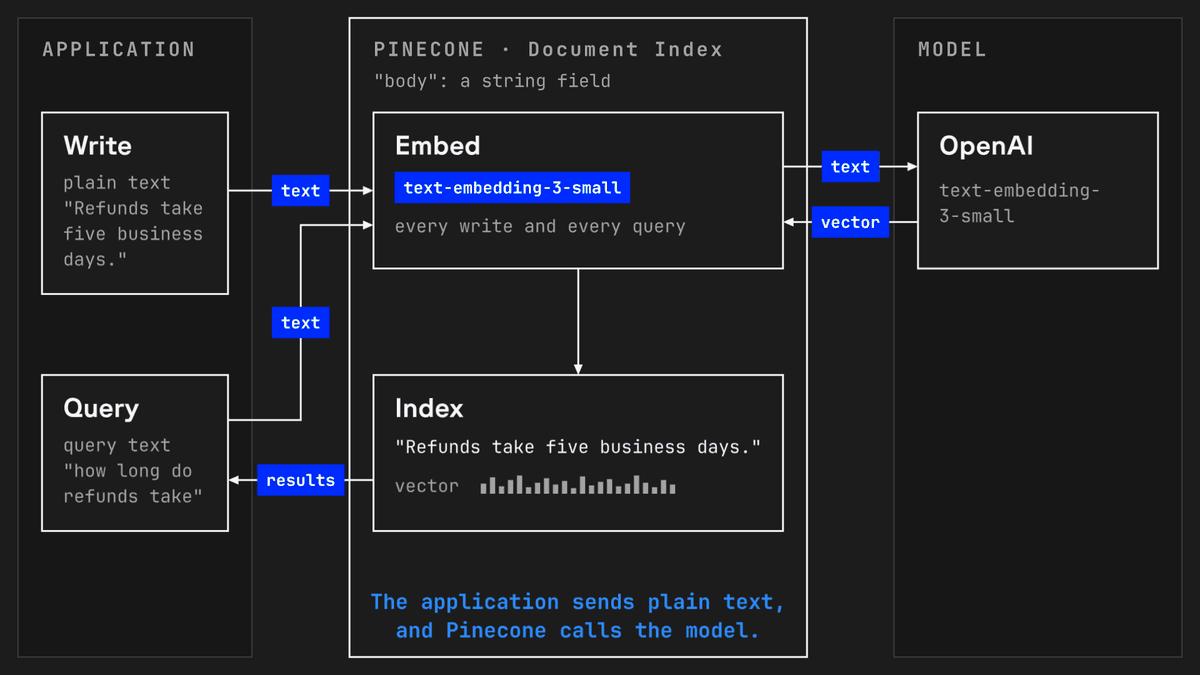
Using an OpenAI embedding model means calling OpenAI's API on every write and every query. Development teams manage the OpenAI account, API key, and rate limits, and pay OpenAI separately from Pinecone. Integrated embedding moves that work into Pinecone:
- Send plain text instead of calling an embedding provider first. Pinecone embeds the query and runs the search in one call.
- Pinecone writes each document's text and its embedding together, so full-text and semantic search always see the same version of each document.
- Pinecone serves OpenAI's models from Microsoft Azure, with traffic spread across several Azure regions. When a region returns errors or slows down, Pinecone automatically retries requests in another region within the same processing location and shifts traffic away until the region recovers, so teams don't have to build their own failover.
- There's no OpenAI API key to manage, and no separate bill for embedding. Tokens are billed on the Pinecone invoice at OpenAI's list price.
How to use OpenAI's text-embedding-3 models in Pinecone
Set the model in the embed setting of a text field when creating a Documents API index. The Python example below embeds the body field with text-embedding-3-small at 1,536 dimensions and turns on full-text search for body, so the same field serves semantic and keyword search.
from pinecone import Pinecone

pc = Pinecone(api_key="YOUR_API_KEY")

pc.indexes.create(
    name="support-articles",
    schema={
        "fields": {
            "body": {
                "type": "string",
                "full_text_search": {},
                "embed": {
                    "model": "text-embedding-3-small",
                    "dimension": 1536,
                },
            }
        }
    },
)

index = pc.index("support-articles")

index.documents.upsert(
    namespace="articles",
    documents=[
        {"_id": "kb-205", "body": "Refunds take five business days."},
    ],
)
To search, send the query as text:
results = index.documents.search(
    namespace="articles",
    top_k=5,
    score_by=[
        {
            "type": "embed",
            "fields": ["body"],
            "query": "how long do refunds take",
        }
    ],
    include_fields=["body"],
)
If you leave out the dimension, the field uses the model's full size. Any size the model supports works, so you can keep the dimensions your existing indexes already use.
The OpenAI models Pinecone provides process text globally by default, or only in the United States when the field uses the US processing location. They're available on every plan, with the US processing location on the Standard plan and above.
| Model | Dimensions | Default dimension | Processing location |
|---|---|---|---|
| text-embedding-3-small | 1 to 1,536 | 1,536 | Global or US |
| text-embedding-3-large | 1 to 3,072 | 3,072 | Global or US |
Availability and limits
- The models work on serverless Documents API indexes. BYOC, pod-based, and Records API indexes aren't supported.
- The console and Python SDK 10.3.0 support these models. Support in the Node.js and Go SDKs is coming soon.
- Existing vector indexes can be converted to Documents API indexes without re-embedding. Adding integrated embedding to a converted index is coming soon. Until then, use these models on new Documents API indexes and send them your text.
- Starter plan includes 5M tokens a month for each OpenAI model, and Builder plan includes 10M a month for each. Both plans get twice that through December 31, 2026.
Get started
Read the integrated embedding docs to learn how to set up OpenAI's text-embedding-3 models on a Documents API index. Through December 31, 2026, Starter and Builder plans get twice their included tokens for OpenAI's models: 10M a month on each model for Starter and 20M a month on each model for Builder.
Was this article helpful?